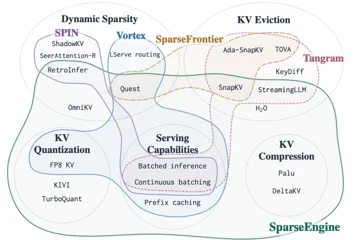
从 KV 管理到 Chain Cache,让稀疏方法真正参与推理引擎的执行与跨轮缓存复用。
Blog博客
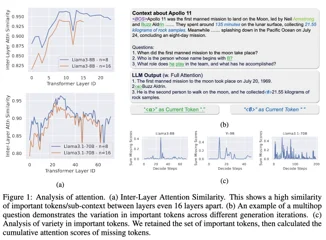
保留完整 KV,动态选择注意力上下文;以及这一思路在 IndexCache 中的延伸。
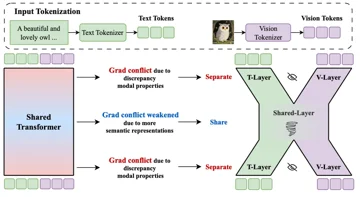
从文本与视觉的梯度冲突出发,探索统一理解、生成和编辑的自回归架构。
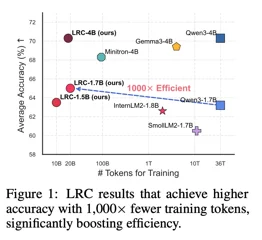
把 FFN 看作 Key-Value Memory,用低秩投影与激活克隆将教师的知识带入小模型。
From KV management to Chain Cache: making sparse methods part of engine execution and cache reuse across turns.
Retain the full KV cache while selecting attention context dynamically, with later developments in IndexCache.
An autoregressive architecture for unified understanding, generation, and editing, motivated by text–vision gradient conflict.
Treating FFNs as key-value memories, and transferring their knowledge through low-rank projection and activation clone.